Audience: This post assumes familiarity with JavaScript and basic backend concepts. It’s aimed at developers who use Node.js but want to understand what’s actually happening under the hood.
TL;DR: Node.js uses a single-threaded event loop to manage concurrency. Instead of spawning a new thread per request, it delegates I/O tasks to background workers (via libuv) and processes results when they’re ready. This is concurrency without parallelism — and it scales surprisingly well for I/O-bound workloads.
Problem
Most developers coming from Java or Python expect a web server to spawn a new thread for each incoming request. When they learn Node.js uses a single thread, the obvious question is: how does it handle 10,000 simultaneous connections without grinding to a halt?
The answer isn’t magic — it’s a specific architectural decision around how I/O is handled. Understanding it will help you write better Node.js code and know exactly where the model breaks down.
Mental Model: The Chef Analogy
Imagine a restaurant kitchen with one chef (your single thread) and a team of kitchen assistants (background workers).
- A customer order comes in → the chef reads it
- If the task requires waiting (boiling water, baking in the oven) → the chef hands it off to an assistant and immediately moves to the next order
- When the assistant finishes → they ring a bell → the chef picks up the result and plates the dish
The chef is never idle waiting for water to boil. They’re always processing the next available task. This is concurrency — many tasks in progress at once — not parallelism (many tasks running simultaneously on multiple CPUs).
Node.js works the same way.
Solution: How It Actually Works
The Single Thread
Node.js runs your JavaScript on a single thread powered by V8 (Chrome’s JS engine). This thread runs the event loop.
A thread is a sequence of instructions a CPU executes. A process can have multiple threads. Most traditional servers (Apache, Tomcat) use one thread per request — which means memory and context-switching overhead at scale.
Node.js takes a different approach: one thread, non-blocking I/O.
Step 1: The Event Loop
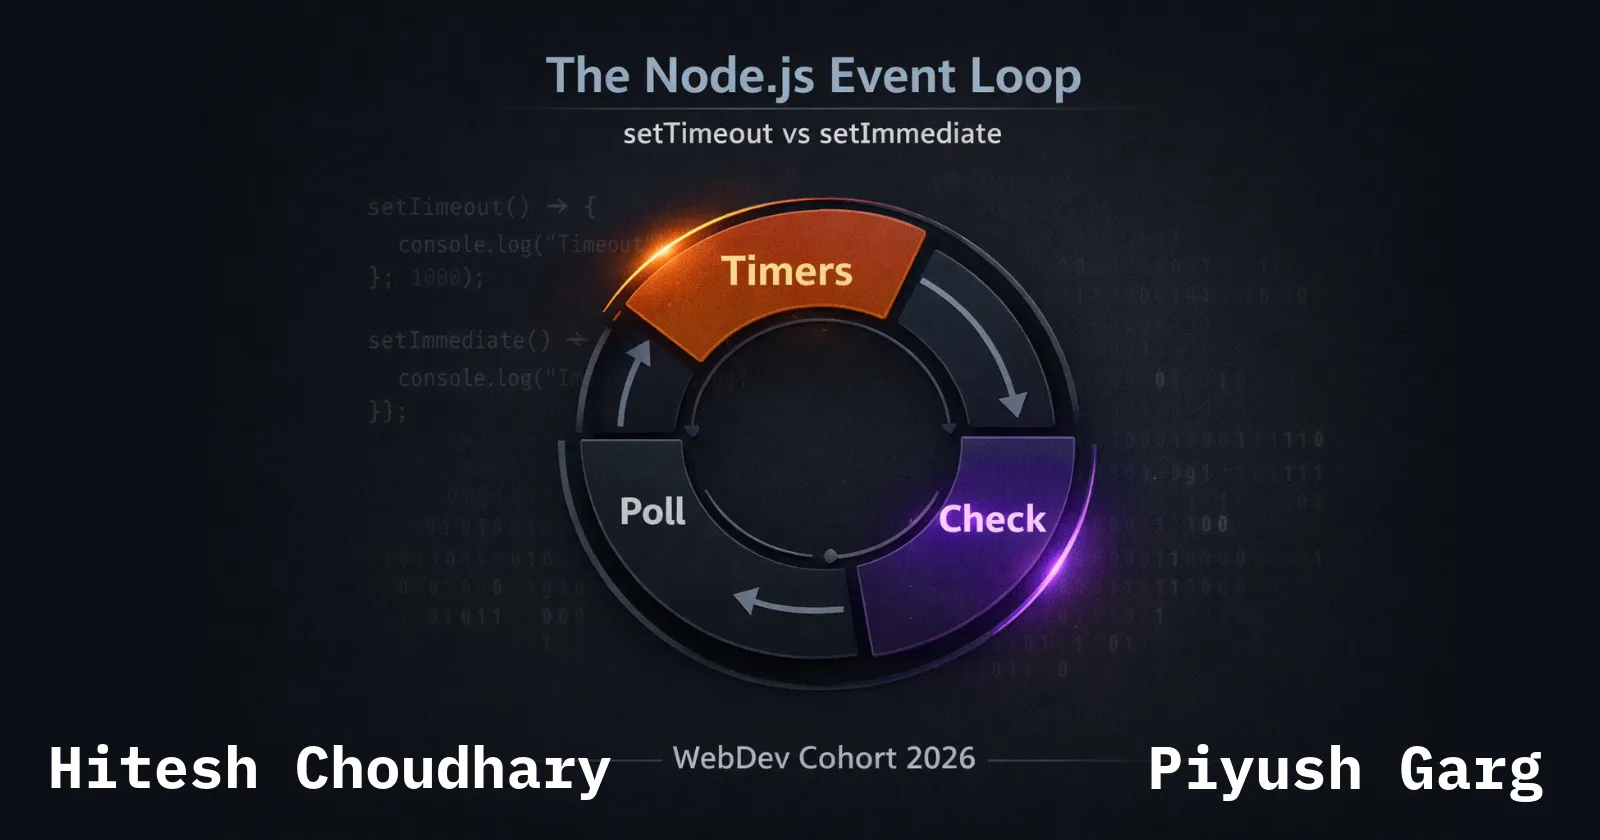
The event loop is the core of Node.js’s concurrency model. It’s a loop that continuously checks for tasks to execute.
Here’s a simplified version of what the event loop does on each iteration (called a “tick”):
┌─────────────────────────────────────────────┐
│              Event Loop Tick                │
│                                             │
│  1. timers        (setTimeout, setInterval) │
│  2. I/O callbacks (completed I/O ops)       │
│  3. idle/prepare  (internal use)            │
│  4. poll          (wait for new I/O events) │
│  5. check         (setImmediate callbacks)  │
│  6. close cbs     (socket.on('close', ...)) │
└─────────────────────────────────────────────┘
The poll phase is where most of the waiting happens. If there are no callbacks to process, the loop waits here for incoming I/O events.
Step 2: Non-Blocking I/O via libuv
Node.js is built on libuv, a C library that handles asynchronous I/O. When your code does something like reading a file or making a database query, libuv takes over.
// server.js — Handling file read without blocking the thread
const http = require('http');
const fs = require('fs');

const server = http.createServer((req, res) => {
  if (req.url === '/report') {
    // This does NOT block the thread
    // libuv delegates this to the OS or thread pool
    fs.readFile('./report.json', 'utf8', (err, data) => {
      if (err) {
        res.writeHead(500);
        res.end('Error reading file');
        return;
      }
      res.writeHead(200, { 'Content-Type': 'application/json' });
      res.end(data);
    });
  } else {
    res.writeHead(200);
    res.end('OK');
  }
});

server.listen(3000, () => {
  console.log('Server running on http://localhost:3000');
});
When fs.readFile is called:
- Node.js hands the task to libuv
- libuv either uses the OS’s async I/O (epoll on Linux, kqueue on macOS) or its own internal thread pool (default size: 4 threads)
- The main thread is free to handle other requests
- When the file is read, libuv pushes the callback into the event loop queue
- The event loop picks it up and executes the callback
Step 3: Handling Multiple Concurrent Requests
Let’s make this concrete. Run the server above and simulate 5 simultaneous requests:
// load-test.js — Simulate 5 concurrent requests
const http = require('http');

const makeRequest = (id) => {
  const start = Date.now();
  http.get('http://localhost:3000/report', (res) => {
    let data = '';
    res.on('data', (chunk) => { data += chunk; });
    res.on('end', () => {
      console.log(`Request ${id} completed in ${Date.now() - start}ms`);
    });
  });
};

for (let i = 1; i <= 5; i++) {
  makeRequest(i);
}
Expected Output:
Request 3 completed in 12ms
Request 1 completed in 14ms
Request 5 completed in 14ms
Request 2 completed in 15ms
Request 4 completed in 16ms
All 5 requests complete in ~15ms total — not 5 × 15ms = 75ms. They ran concurrently on a single thread.
Concurrency vs Parallelism
Node.js achieves concurrency, not parallelism.
- Parallelism: Multiple operations literally executing at the same moment on multiple CPU cores (threads/processes).
- Concurrency: Multiple operations in progress at the same time, but not necessarily executing simultaneously. Progress is interleaved.
Node.js can have thousands of database queries pending at once, all waiting for responses. But your JavaScript itself runs on one thread. When a response arrives, its callback executes, then yields back to the event loop. That is why the next two sections matter: some work leaves the main thread (the thread pool), and some work never should have been on it (CPU-bound code).
Step 4: The libuv Thread Pool (Background Workers)
Not everything can use the OS’s async I/O. Operations like DNS lookups, file system work, and some crypto operations use libuv’s internal thread pool.
┌──────────────────────────────────────────────────────┐
│                    Node.js Process                   │
│                                                      │
│  ┌─────────────┐        ┌──────────────────────────┐ │
│  │ Main Thread │◄──────►│     libuv Event Queue    │ │
│  │ (Event Loop)│        └──────────────────────────┘ │
│  └──────┬──────┘                   ▲                 │
│         │ delegates I/O            │ callback ready  │
│         ▼                          │                 │
│  ┌─────────────────────────────────┴──────┐          │
│  │         libuv Thread Pool             │          │
│  │  Worker 1 | Worker 2 | Worker 3 | W4  │          │
│  └────────────────────────────────────────┘          │
└──────────────────────────────────────────────────────┘
You can increase the thread pool size with an environment variable:
UV_THREADPOOL_SIZE=16 node server.jsThis is useful if your app does heavy file I/O or DNS resolution and you’re seeing thread pool saturation.
Step 5: What Blocks the Event Loop (The Real Danger)
The single-thread model has one critical weakness: CPU-bound work blocks everything.
// DANGEROUS: This blocks the event loop for ~3 seconds
// No other request can be handled during this time
const http = require('http');

const blockingComputation = () => {
  const end = Date.now() + 3000; // block for 3 seconds
  while (Date.now() < end) {}    // busy wait — never do this
  return 'done';
};

const server = http.createServer((req, res) => {
  if (req.url === '/heavy') {
    const result = blockingComputation(); // BLOCKS EVERYTHING
    res.end(result);
  } else {
    res.end('fast response');
  }
});

server.listen(3000);
If one request hits /heavy, every other request waits 3 seconds. The chef analogy: your chef got stuck actually watching the pot boil instead of delegating.
The fix: Use Worker Threads for CPU-intensive work.
// worker-server.js — Offload CPU work to a Worker Thread
const http = require('http');
const { Worker, isMainThread, parentPort, workerData } = require('worker_threads');
const path = require('path');

if (isMainThread) {
  const server = http.createServer((req, res) => {
    if (req.url === '/heavy') {
      // Spawn a worker thread — does NOT block the event loop
      const worker = new Worker(__filename, {
        workerData: { task: 'compute' }
      });

      worker.on('message', (result) => {
        res.end(`Result: ${result}`);
      });

      worker.on('error', (err) => {
        res.writeHead(500);
        res.end(err.message);
      });
    } else {
      res.end('fast response'); // still responds instantly
    }
  });

  server.listen(3000, () => console.log('Server on port 3000'));
} else {
  // This runs inside the worker thread
  let result = 0;
  for (let i = 0; i < 1e9; i++) {
    result += i;
  }
  parentPort.postMessage(result);
}
Now the heavy computation runs in a separate thread, and the event loop remains free to handle other requests.
Why Node.js Scales Well for I/O-Bound Workloads
Traditional thread-per-request servers have an upper bound defined by memory and thread overhead: every thread needs its own stack, and the OS has to schedule and context-switch between all of them.
Node.js with non-blocking I/O keeps one JavaScript thread alive. An open connection that is waiting on I/O costs a small object in memory, not a whole thread, so the number of connections you can hold open is limited by memory per connection rather than by thread count.
Results
| Scenario | Thread-per-request | Node.js Event Loop |
|---|---|---|
| Many idle concurrent connections | One thread (and its stack) per connection | One thread for all connections |
| I/O wait time (DB query) | Thread sits idle | Thread handles other requests |
| CPU-bound task | Handled in separate thread | Blocks event loop unless offloaded |
| Context switching | High (OS scheduler overhead) | Minimal |
Trade-offs
Where Node.js excels:
- REST APIs with database queries
- Real-time apps (WebSockets, chat)
- Streaming data pipelines
- Microservices with high concurrency
Where Node.js struggles:
- Image/video processing
- Machine learning inference
- Heavy cryptographic operations
- Anything CPU-bound that can’t be offloaded
The thread pool is small by default. If 4 concurrent fs.readFile calls saturate the pool, the 5th queues behind them. Monitor this in production with tools like clinic.js or 0x.
Unhandled errors crash the process. One uncaught exception on the single thread can bring down the entire server. Use process managers like PM2 and always handle process.on('uncaughtException') and process.on('unhandledRejection').
Conclusion
Node.js achieves concurrency on a single thread by never waiting — it delegates I/O to libuv, which uses OS-level async mechanisms or a background thread pool. The event loop continuously picks up completed callbacks and processes them.
The model works extremely well for I/O-bound workloads and poorly for CPU-bound ones. The fix for CPU-bound tasks isn’t to abandon Node.js — it’s to use Worker Threads to keep the event loop free.
Understanding this architecture tells you exactly when to use Node.js, when to offload work, and why your server might be slow when you thought it shouldn’t be.
Next step: Profile your Node.js app with node --prof server.js and use node --prof-process to find where CPU time is actually being spent.